
Seedance 2.5 提示词指南:如何写出真正有效的提示词
Seedance 2.5 提示词采用四段式分镜表效果最好。了解如何编写时间戳、绑定参考图,以及把控声音、对白与运镜。
 The Seadanse Team14 分钟阅读
The team behind Seadanse. We run the models we write about, and we publish the specs, prices and limits the marketing leaves out.

TL;DR — 一条标准的 Seedance 2.5 提示词就是一个四段式分镜表:指定文件对应关系、一句话概括、带时间戳的情节,以及必须保持一致的规则。如果你刚从 Seedance 2.0 转过来,请把以前写的“Shot 1”换成“0-3 seconds”。除非你明确要求关闭,否则音频默认开启,因此最好在提示词中自行写明声音需求。
你在视频生成器里输入了一句写得很好的话,满怀期待地等待成片,结果却生成了一段长达 30 秒、完全不相干的内容。遇到这种情况,并不是模型出错了,它只是在为你留下的空白处自行脑补而已。
这种“脑补”的代价相当高昂。一段 30 秒视频的成本是 5 秒视频的 6 倍,盲目的试错会迅速耗光你的积分。你可以在我们的定价页面上的积分计算器中查看不同时长的积分消耗规则。
想要稳定生成符合预期的成片,你必须按照模型真正解析的结构来撰写提示词。
ByteDance 已经公开了 Seedance 2.5 所期望的提示词结构。一旦你理解了 Seedance 2.5 有何不同,写出有效的提示词就会变得非常简单。下文提供了 6 个可直接复制运行的提示词,其中两个来自社区创作者。
Seedance 2.5 提示词的四个板块
ByteDance 建议创作者像对待制作人一样对待该模型:“将 Seedance 2.5 视为视觉内容制作人,以视觉叙事的思维方式撰写结构化提示词。”(Treat Seedance 2.5 as a visual content producer, and write structured prompts with a visual storytelling mindset.)
官方指南将提示词划分为四个板块:
- 指定文件对应关系: 按上传顺序和角色明确标注每一个图片、视频或音频文件。
- 一句话概括: 按“主体 + 地点 + 事件 + 类型/风格 + 运镜…”的格式撰写。
- 带时间戳的情节: 将整段视频拆解为具体的时间段,并注明具体的视觉画面、动作、运镜轨迹与对白。
- 必须保持一致的规则: 列出跨镜头切换时必须保持一致的视觉规则,如光影、环境和构图。
我们可以将这些规则整理为一个实用的五行公式:
| 板块 | 填写内容 | 示例片段 |
|---|---|---|
| 指定文件对应关系 | 按上传顺序,每张图片写一行说明 | “图 1 是潜水员,身穿黄色干式潜水服,佩戴有划痕的头盔。” |
| 一句话概括 | 主体、地点、事件、风格、运镜 | “黎明时分,一名潜水员在港口防波堤旁浮出水面,手持长镜头一镜到底拍摄。” |
| 带时间戳的情节 | 带时间码的分镜拍,每拍包含画面、镜头、动作与声音 | “0-4 秒。远景,他破水而出;海鸥鸣叫,海面平缓。” |
| 声音 | 放在引号内的对白,随后是环境音与音乐 | “他说:‘不在下面。’海浪拍打石壁声,无音乐。” |
| 必须保持一致的规则 | 整条片子中不得发生漂移的要素 | “面部一致、同一套潜水服、相同的灰色冷光、一镜到底。” |
这五个板块遵循了 ByteDance 官方发布的提示词结构;示例片段为我们所写。
生成简单的镜头并不需要填满每一行。但保持这一标准顺序,有助于 Seadanse 上的 Seedance 2.5 准确理解你的意图,避免产生混淆。
在 Seadanse 上写下你的第一条提示词
在 Seadanse 上生成视频只需几步:
- 将你的结构化提示词粘贴到 Seedance 2.5 AI 视频生成器 的输入框中。
- 选择分辨率:480p、720p 或 1080p。
- 选择生成时长:5、10、15、20、25 或 30 秒。
- 从 6 种宽高比中任选其一。
- 点击“生成”。
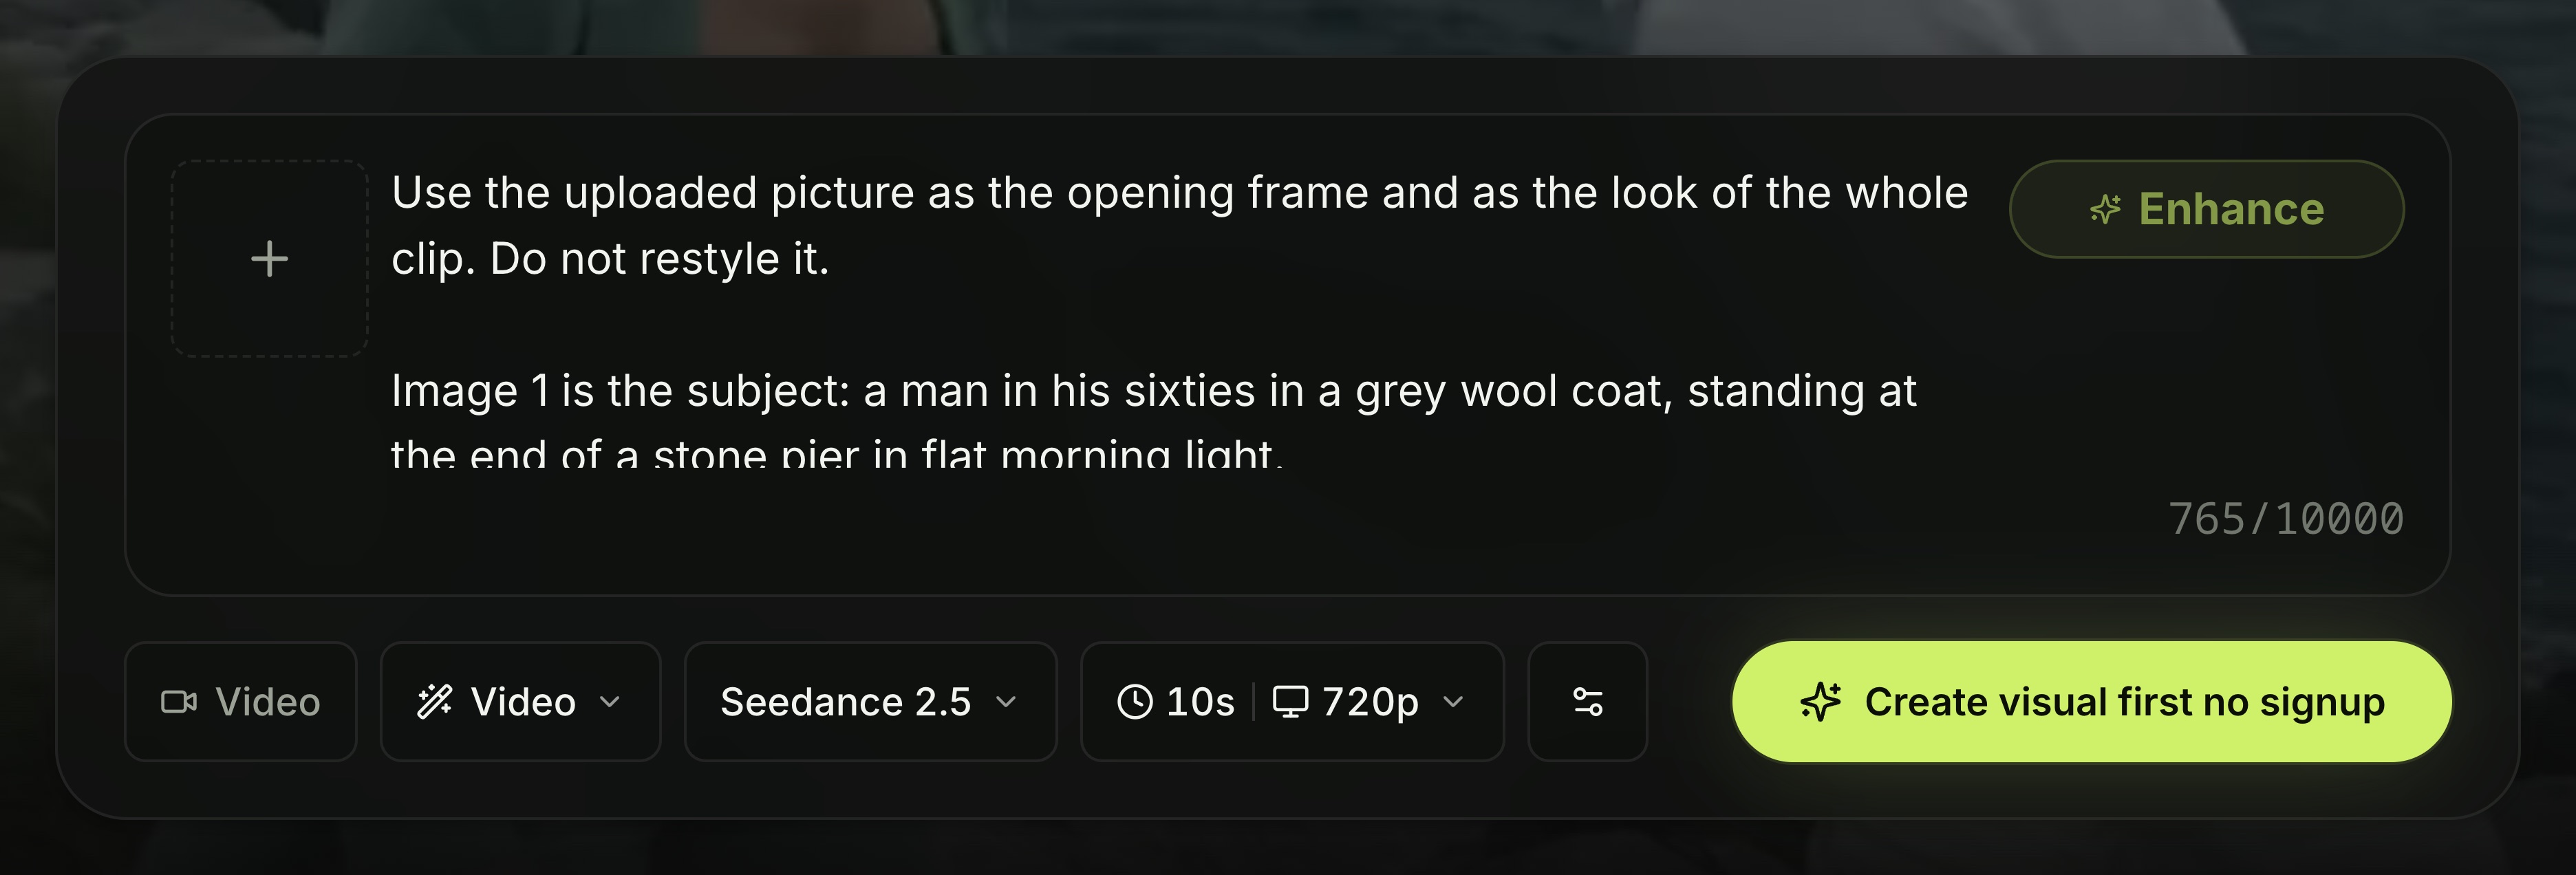
粘贴了提示词 3 的编辑界面,参数设置为 720p、10 秒——截图截取于 2026年8月19日。
在 Seadanse 上,Seedance 2.5 是默认的模型预设。提示词输入框最多支持 10,000 个字符。
如果你只有一个粗略的想法,可以点击输入框中的“增强”(Enhance)按钮。它会将你的粗糙文本重写为包含开篇风格、编号分镜拍和声音指令的分镜表,并保留你用引号引用的任何原语言对白。
在相同生成时长下,720p 视频的积分成本大约是 480p 的 2.2 倍;1080p 视频的成本大约是 480p 的 3.9 倍。点击生成前,你可以在“生成”按钮上直接看到确切的积分消耗。
以下是平台的积分使用规则:
- 如果生成失败,你的积分会自动退还。
- 新注册账号无需绑定信用卡,即可获赠免费起步积分。
- 你可以购买 $9.9 的积分包,无需按月订阅。
- 购买的积分有效期为 12 个月,导出的成片没有任何水印。
打开 Seedance 2.5 生成器,开始制作你的第一条视频。
Seedance 2.0 无法实现的时间戳控制
Seedance 2.5 最大的功能性突破在于对时间轴的真正精准控制。正如 Tim Simmons 在其 2026年8月5日 Theoretically Media 评测视频 中所指出的:“2.5 的提示词完全是另一套逻辑,你以前用在 2.0 上的部分提示词根本无法直接迁移过来”(prompting in 2.5 is a bit of a different beast and some of your 2.0 prompts will not translate very well over)。
像 Seedance 2.0 这样的老款模型只能识别镜头编号标签。而 Seedance 2.5 则以 1 秒为基本单位,能够精准识别整秒级的时间戳。
该模型支持三种时间戳格式:
- 时间区间: 写入明确的时间跨度,如
0-3 seconds...3-7 seconds...7-15 seconds或[1s-4s]....[4s-8s]....[8s-12s]。 - 时间锚点: 锁定特定瞬间,例如“在第 5 秒处向左快速平移转场”。
- 相对时间: 将分镜拍串联起来,例如“John 茫然地站在那里。3 秒后,周围的人都朝他摇了摇头”。
编写时间轴时,有两种常见错误会导致成片崩坏:
- 时间线断档: 如果你的提示词从
0-3s...直接跳到5-6s...,模型在处理未描述的空白间隙时就会表现挣扎。 - 节奏脱节: 如果你在很长的时间跨度内安排了过少的动作,模型就会自由发挥脑补;如果你在短短几秒钟内塞入太多情节,画面要么疯狂跳切,要么干脆遗漏你的关键拍。
切勿使用时间戳来指挥极快的高频动作。要求模型“每秒摇头三次”是无法生效的。
| 过去在旧模型中的写法 | 在 Seedance 2.5 中的写法 | 对你的实际意义 |
|---|---|---|
| “Shot 1: … Shot 2: …” | “0-4 seconds: … 4-9 seconds: …” | 2.0 只能读取镜头编号。2.5 可以识别整秒,让你能够掌控每个拍落下的精确节点。 |
| 上传多张未加标注的角色图片 | “Image 1 是潜水员。Image 2 是港务长。” | 未标注的图片容易发生角色特征混淆或重复克隆。 |
| 无声提示词,稍后再补音频 pass | 在提示词中直接嵌入声音指令 | 生成出来的成片直接自带原生音效。 |
| “无模糊、无伪影、无畸变” | 正向描述,需要时补充“无字幕” | 只有字幕和声音可以接受负向提示词。 |
Seedance 2.5 支持读取整秒级时间戳,而 2.0 则不支持。
用数字绑定每一个参考素材
所谓“参考素材绑定”,就是明确告诉模型上传的哪张图片对应哪个角色、物体或风格。Seedance 2.5 要求根据你的上传顺序,进行显式的数字编号绑定。
编写清晰明了的单行绑定指令:
- “Image 1 中的骑士”
- “Image 1-2 为角色 1,对应 Audio 1;Image 3-4 为角色 2,对应 Audio 2。”
- “光影与滤镜参考 Image 1。”
不要直接把名字或标签打在参考图上。如果你在图片上印上“John”,然后在提示词里写“John 正在学校”,模型很容易产生困惑并复制出多个角色。
在深度体验了几天该模型后,Min Choi 总结道:优秀的提示词大部分是约束条件——“提示词不是用来泛泛描述的,它们主要用于施加约束。”(The prompts aren't descriptions. They're mostly restrictions.)他还补充道:“一张优质的参考图胜过五张平庸的参考图。”(One good reference beats five mediocre ones.)
当参考视频片段中已经包含你想要的动作时,就不要过度描述细节。官方文档明确指出,如果你写下“严格参考 Video 1 中的动作与运镜,并保持动作顺序与视频完全一致”,你就不需要再单独细致描述抬手或镜头运动了。
Seedance 2.5 支持为同一主体输入多视角照片。ByteDance 过去并不建议在 2.0 上使用此类操作。
在 API 层级,Seedance 2.5 最多支持 50 个文件输入(30 张图片、10 个视频、10 个音频文件),而 2.0 仅支持 15 个。
在 Seedance 2.5 上,你可以提交图片和参考视频片段。图片可用于文生视频、图生视频以及首尾帧模式;当你需要复用画面中已有的特定动作或镜头运动时,就可以使用参考视频片段。参考音频是目前暂不支持的输入项,因此角色的音色必须通过文字描述来指定,而不是直接复制音频素材。
写明声音,否则模型会替你做主
Seedance 2.5 可以在单次推理中同步生成视频与音频。它能够同时生成对白、背景环境音以及配乐。
在 Seadanse 上,音频功能默认开启。如果在提示词中完全不写声音需求,模型就会自行脑补背景杂音和配乐。
如果需要指定台词,请将对白放进引号中,并明确指定说话人:
Mara says, "You still keep your receipts in the pocket."它原生支持生成 10 多种语言的语音。
默认情况下,模型往往会在生成语音的同时打上屏幕字幕。如果你不希望画面上出现文字,请在提示词中加上“No subtitles.”。
在对 44 个可用提示词的统计中,有 45% 的提示词直接在正文中写明了声音指令。而在老旧的 2.0 提示词中,仅有 19% 包含声音。由于 2.5 具备原生音效生成能力,声音指导不再是可有可无的附属品。
模型已原生掌握的运镜词汇
你可以直接使用标准的电影拍摄术语,模型可以无障碍解析。
使用标准的景别与拍摄角度:
- 极远景(Extreme wide shot)、远景(wide shot)、中景(medium shot)、中特写(medium close-up)、特写(close-up)
- 低角度仰拍、俯拍、第一人称视角(first-person perspective)
使用标准的运镜手法与技巧:
- 推镜头(Push in)、拉镜头(pull out)、摇镜头(pan)、横移跟拍、跟随运镜(follow)、环绕运镜(orbit)、俯冲(dive)、后拉(pull back)、上倾摇镜(tilt up)、手持晃动(handheld shake)
- 一镜到底或长镜头(One-shot or long take)、希区柯克变焦(Hitchcock zoom 或 dolly zoom)、航拍视角(aerial perspective)、FPV、子弹时间(bullet time)、手持镜头(handheld shot)、变速升降格(speed ramp)
如果需要使用冷门或特殊的运镜手法,请采用 [术语 + 描述性解释] 的结构,例如:“焦点转移(Rack focus):焦点平滑过渡;前景中原本清晰的树木逐渐变模糊,背景中的角色逐渐变清晰。”
在提示转场时,请同时注明时间和具体方式:“在第 5 秒处,镜头采用向左擦除配合自然叠化快速向左转场。”
对动作的描述尽量保持概括。只针对你最在乎的一两个瞬间进行细节刻画,而不要去细抠每一个微动作。对于面部表情,尽量使用描述性的具体陈述句,而不是成语或抽象修辞。你可以在 Seedance 2.5 视频生成器 中实测这些镜头的呈现效果。
负向提示词仅对字幕与声音生效
有时你需要要求画面中不要出现某些元素,这就是负向控制。
在 Seedance 2.5 中,没有专门的负向提示词输入框。该模型仅针对以下两类情况接受否定句式:
- 字幕: “Do not add subtitles.” 或 “No subtitles.”
- 音频: “No BGM; generate only environmental sounds and action sounds.” 或 “No audio.”
不要在提示词里堆砌诸如“无模糊、无低画质、无多余肢体、无畸变人体”这类的套话。模型根本不会理会。
ByteDance 建议创作者尽量使用正向描述。重点描述画面中应该出现什么,而不是不该出现什么。
6 个可直接复制的提示词模板
以下提供 6 个可以直接复制运行的提示词,覆盖了不同的生成模式与宽高比。
前两个提示词并非我们原创。作者将它们与生成的成片一起发布在 X 上,收录在我们的 Seedance 2.5 提示词库 中,文字未作任何改动。你看到的内容就是模型当时读取的原始字符。其余 4 个提示词由我们撰写,专门针对词库未覆盖的模式设计。
1. 包含 4 句台词的产品评测视频
本案例来自 @AIwithkhan,发布于 2026年8月4日。我们未作任何字句改动。
Use the uploaded reference image as the exact character reference. Preserve her facial identity, hairstyle, eye color, makeup, skin tone, body proportions, white sleeveless fitted top, light blue wide-leg jeans, pearl choker, rings, and bracelets consistently throughout the video. Use the uploaded sunglasses, retail box, and leather carrying case as locked product references. Maintain perfect product consistency, including the frame shape, lenses, hinges, colors, materials, and proportions.

Create an ultra-realistic UGC luxury creator review filmed inside a modern luxury bedroom with warm golden-hour sunlight, soft natural shadows, and a premium lifestyle aesthetic. The camera feels like a handheld smartphone with subtle natural movement while maintaining cinematic commercial quality.

The video begins with the woman sitting on the bed beside the retail box and leather case. Smiling at the camera, she says, "I genuinely wasn't expecting to love these this much." She picks up the box, opens it naturally, reveals the leather case, then slowly removes the sunglasses while continuing, "The packaging already feels incredibly premium."

She rotates the sunglasses slowly in front of the camera, showing the frame, hinges, and lenses as natural reflections glide across the surface. She smiles and says, "The finish feels amazing, and they're incredibly lightweight."

She puts on the sunglasses, stands up, and walks toward a large full-length mirror. Looking at her reflection, she adjusts the frame naturally and says, "Honestly... they look so good, and they're really comfortable on the eyes, even in bright sunlight."

She turns slightly left and right so the sunglasses catch the sunlight from different angles before removing them with a smile. Walking back to the bed, she places the sunglasses beside the leather case and retail box, then picks them up one last time and holds them beside her face.

Looking directly into the camera, she smiles warmly and says, "Definitely one of my favorite accessories this year." The camera slowly pushes in on the sunglasses before fading out.

Ultra-realistic UGC fashion content, authentic creator review, cinematic handheld smartphone movement, luxury bedroom, macro product cinematography, realistic reflections, detailed frame textures, expressive facial animation, perfect lip sync, shallow depth of field, premium color grading, 4K HDR, 16:9, no subtitles, no logos, no watermarks, no on-screen text.由 @AIwithkhan 使用 Seedance 2.5 制作,2026年8月4日——15 秒,16:9。上方提示词为原作者撰写,未作编辑。
注意第一段的作用。它完全没有描述具体场景,而是列出了绝不能走样的要素:她的长相、穿着,以及精确到铰链结构的产品细节。只要将这些必须保持一致的规则锁定,后续的所有动作就可以自由发挥。
4 句台词各自精准穿插在对应的动作指令之中。提示词以“no subtitles, no logos, no watermarks, no on-screen text”收尾——这正是模型唯一能够解析的负向控制语句。
2. 带有精准时间轴对白的 30 秒短片
本案例来自 @bmx_ai13,发布于 2026年7月31日,逐字保留原貌。
Create a 30 second cinematic short film titled The Suit Was Still Listening, presented in 16:9 with synchronized dialogue, environmental sound, and original music. The film must feel completely live action, physically grounded, and captured on location, never glossy or synthetic.

Visual language: a rain soaked neighborhood laundromat at midnight, warm amber fluorescent tubes inside, cold blue street light and moving car reflections outside, wet pavement, fogged windows, chipped enamel machines, baskets, detergent boxes, loose receipts, realistic skin texture, natural eye moisture, subtle fabric lint, imperfect hair, restrained film grain, gentle halation, lifted shadows, rich but believable color. Wardrobe creates bold editorial color blocking: Mara wears a cobalt trench over a cream blouse, Noah wears a rust knit polo, the teenage attendant wears faded green workwear, and an elderly customer wears a pale gray suit and dark hat. Use expressive medium close shots, tactile inserts, occasional low angles, clean profile compositions, and brief handheld movement that feels operated by a human. Preserve consistent faces, clothing, props, screen direction, reflections, hand anatomy, and spatial continuity. Use realistic speech timing, breathing, blinking, eye focus, and precise lip synchronization.

0 to 3 seconds. Exterior wide shot through falling rain. A lonely laundromat glows on a dark corner. A black sedan turns slowly into the street. Camera makes a subtle forward creep. Music begins with muted upright bass, brushed snare, a low analog pulse, and the rhythmic churn of washers.

3 to 6 seconds. Interior macro shot through a round washer door. A red scarf turns through soap and water. Cut to Mara opening a dryer. A tiny black transmitter falls from the lining of a cream suit and strikes the tile with a sharp metallic click. The score briefly drops out.

6 to 10 seconds. Low medium two shot. Noah freezes beside a folding table. He says quietly, You said clean the suit. Mara studies the transmitter in her palm and replies, I did. You hid a heartbeat in the lining. Keep the delivery controlled and intimate, not theatrical.

10 to 14 seconds. Tight insert on the teenage attendant checking an old signal meter beside the change machine. A green needle jumps. He looks toward the fogged front window and says, It is still transmitting. Camera racks focus from the meter to white headlights sliding across the glass.

14 to 18 seconds. The sedan stops outside. The elderly customer continues folding a shirt without looking up. He says, Then he is already here. Hold on Mara as the moving headlights carve across her face. Let silence, rain, and machine motors carry the tension.

18 to 22 seconds. Noah whispers, Back door. The old man calmly turns the deadbolt on the back exit and answers, Too obvious. Mara notices a delivery rider outside pushing a rolling laundry cart past the window. Use a fast sequence of close shots: her eyes, the transmitter, the cart wheel, the sedan mirror.

22 to 27 seconds. Mara crosses naturally behind a row of machines, slips the transmitter into a sealed laundry bag on the moving cart through an open service hatch, and returns without drawing attention. Noah asks, What did you do. Mara watches the cart continue down the wet street and says, Gave him a cleaner story.

27 to 30 seconds. Exterior telephoto view. The black sedan pulls away and follows the cart. Cut back inside to a symmetrical medium shot of the four characters framed by spinning washer doors. The red scarf circles behind Mara like a slow warning light. She sits opposite Noah and says, Now tell me who owns the suit. End on the transmitter signal fading from the attendant meter as the final bass note lands.

Sound design must include rain on glass, distant tires on wet road, washer motors, dryer buttons, fabric movement, the transmitter click, door lock, fluorescent hum, and soft room reflections around every voice. Dialogue must remain clean and naturally mixed above the music. Avoid visual distortion, artificial camera acceleration, floating objects, excessive shallow focus, oversharpening, plastic skin, extra fingers, unreadable signage, random background motion, or dreamlike effects.由 @bmx_ai13 使用 Seedance 2.5 制作,2026年7月31日——30 秒,16:9。上方提示词为原作者撰写,未作编辑。
整条 30 秒的视频被划分为 8 个时间段,每个时间段维持在 3 到 5 秒。作者即便未读过官方指南,也摸索出了指南所倡导的节奏控制。
本例有两个非常值得借鉴的技巧:其一,巧妙利用服装来完成角色绑定——钴蓝色风衣、铁锈色 Polo 衫、褪色绿色工装——即便完全不上传参考图,也能确保 4 个角色各自分明不走样。其二,台词无需加引号,直接嵌入分镜拍的描述中,模型依然能精准对位到角色的口型上。
3. 单图输入,生成 10 秒运镜
Use the uploaded picture as the opening frame and as the look of the whole clip. Do not restyle it.

Image 1 is the subject: a man in his sixties in a grey wool coat, standing at the end of a stone pier in flat morning light.

One continuous ten-second shot, 16:9. The camera starts where the picture starts and pulls back slowly and steadily, so the pier gets longer behind him and the sea opens on both sides. He does not turn around. Around the seventh second he lifts his right hand to his collar and holds it there.

Keep his face, his coat, the pier stones and the light exactly as they are in Image 1. Water moves, the coat moves in the wind, nothing else changes.

Sound: sea against stone, wind across the microphone, gulls far off. No music. No subtitles.使用上述提示词由 Seedance 2.5 制作,附带一张参考图——480p,10 秒,16:9,2026年8月。
该图生视频提示词将 Image 1 直接绑定为起始画面。它没有设计过于复杂的走位,而是要求镜头进行平稳连续的后拉。它指示模型严格保留原图的色彩与质感,仅赋予海浪与大衣自然的动态效果。
4. 5 秒内从指定起始帧过渡到指定结束帧
Image 1 is the first frame. Image 2 is the last frame. Fill the five seconds between them and land exactly on Image 2.

Five seconds, 16:9, one continuous shot, no cuts.

The clip begins on a closed red door in a narrow hallway, lit by one overhead bulb. It ends on the same hallway with the door open and daylight flooding in from behind it.

Write the motion between them: the handle turns, the door swings inward and to the left, and the camera drifts forward at walking pace as the light changes from tungsten yellow to cold daylight across the walls. The bulb stays on and stops mattering as the daylight takes over.

Nothing enters the frame. No people, no hands.

Sound: a latch, hinges, a room tone that opens up when the door does. No music. No subtitles.使用上述提示词由 Seedance 2.5 制作,两张图片作为普通参考素材上传并在提示词中指定——480p,5 秒,16:9,2026年8月。
该提示词指导了 5 秒首尾帧模式的生成,明确界定了两张绑定图片之间的精确镜头推移路径与光影转变过程。
固定首尾帧实际上是对文件本身的属性设定,而不仅依靠提示词语句。每个上传的文件都会附带一个 content.role(告知模型如何使用该文件的标签),例如 first_frame 或 last_frame。官方指南指出:“通过 content.role = first_frame/last_frame 严格控制”(Strictly control this through content.role = first_frame/last_frame),这种做法会将生成画面的宽高比严格锁定为起始图片的比例。这也是 Seadanse 上首尾帧功能底层的运作机制。
此外还有一种相对宽松的做法:将两张图片作为普通参考图上传,仅在提示词文本中进行分配。例如写入“Image 3 是起始帧,Image 5 是结束帧”,这样宽高比和时长依然由你自由掌控,但官方指南警告称,这种方式下成片“会与首帧和尾帧参考图相似,但可能无法完全严丝合缝匹配”(will be similar to the first-frame and last-frame reference images, but may not match them exactly)。如果成片结尾必须百分之百精准落位,请使用绑定的系统角色标签;如果自主控制画面宽高比更重要,在提示词文本中指定即可。
5. 双人角色、两张图片、单场戏
Image 1 is Character 1: a woman in her late twenties, black hair cut short, olive field jacket, a thin scar through her left eyebrow.
Image 2 is Character 2: a man in his fifties, shaved head, wire glasses, grey mechanic's overalls with a name patch.
Match both faces to their pictures in every second of the clip. Do not swap them, do not merge them, do not add a third person.

Fifteen seconds, 16:9, one workshop interior at night, one continuous scene in three beats. Overhead work lamps, oil-stained bench, an engine block on a stand.

0-5 seconds. Wide shot. Character 2 is bent over the bench. Character 1 walks in from the right and stops at the far end of the bench. He does not look up.

5-11 seconds. Medium two-shot. She picks a wrench off the bench and puts it down somewhere else. He straightens up and looks at where she put it. Neither speaks.

11-15 seconds. Close-up on his hands as he moves the wrench back. The camera tilts up to catch her already walking out of frame left.

Throughout: the same faces, the same clothes, the same lamps and shadows, no cuts to another room.

Sound: the hum of the lamps, metal set down on wood, footsteps on concrete. No music. No subtitles.使用上述提示词由 Seedance 2.5 制作,附带两张参考图——480p,15 秒,16:9,2026年8月。
该提示词将两张独立的参考图分别绑定到不同角色上,并通过包含三个时间节点的镜头调度,锁定了全片视觉的一致性。
6. 带有一句台词的 10 秒竖屏广告
A ten-second vertical product clip, 9:16, shot like a phone video in a real kitchen, not like a studio commercial.

0-4 seconds. Handheld medium shot. A woman in her thirties stands at a counter in morning light, holding a plain glass bottle of cold brew. She turns it once so the light catches it. Slight camera wobble, natural.

4-8 seconds. She pours it over ice in a tall glass. Close, from slightly above. Real condensation, real ice movement, no slow motion.

8-10 seconds. She picks up the glass, looks at the camera, and says, "Same as yesterday. That's the point."

Throughout: the same kitchen, the same hands, the same bottle. Warm daylight from a window on the left. No on-screen text of any kind.

Sound: ice, pouring, a fridge running somewhere behind her, her line spoken in English. No music. No subtitles.使用上述提示词由 Seedance 2.5 制作,无参考图——480p,10 秒,9:16,2026年8月。
该提示词设置了 9:16 竖屏比例,模拟自然的手持手机运镜,并将台词精确排布在最后的 2 秒内。
44 个真实的 Seedance 2.5 提示词特征分析
为了解实际有效的提示词到底长什么样,我们做了专项数据统计。我们的提示词库对接了 X 平台上公开收录的 Seedance 帖子。截至 2026年8月19日,该库共收录了 175 条帖子:126 条由 Seedance 2.5 生成,47 条由 Seedance 2.0 生成。在这之中,有 44 条 Seedance 2.5 帖子在成片旁完整附带了提示词正文。这 44 条样本就是我们的统计分析对象。
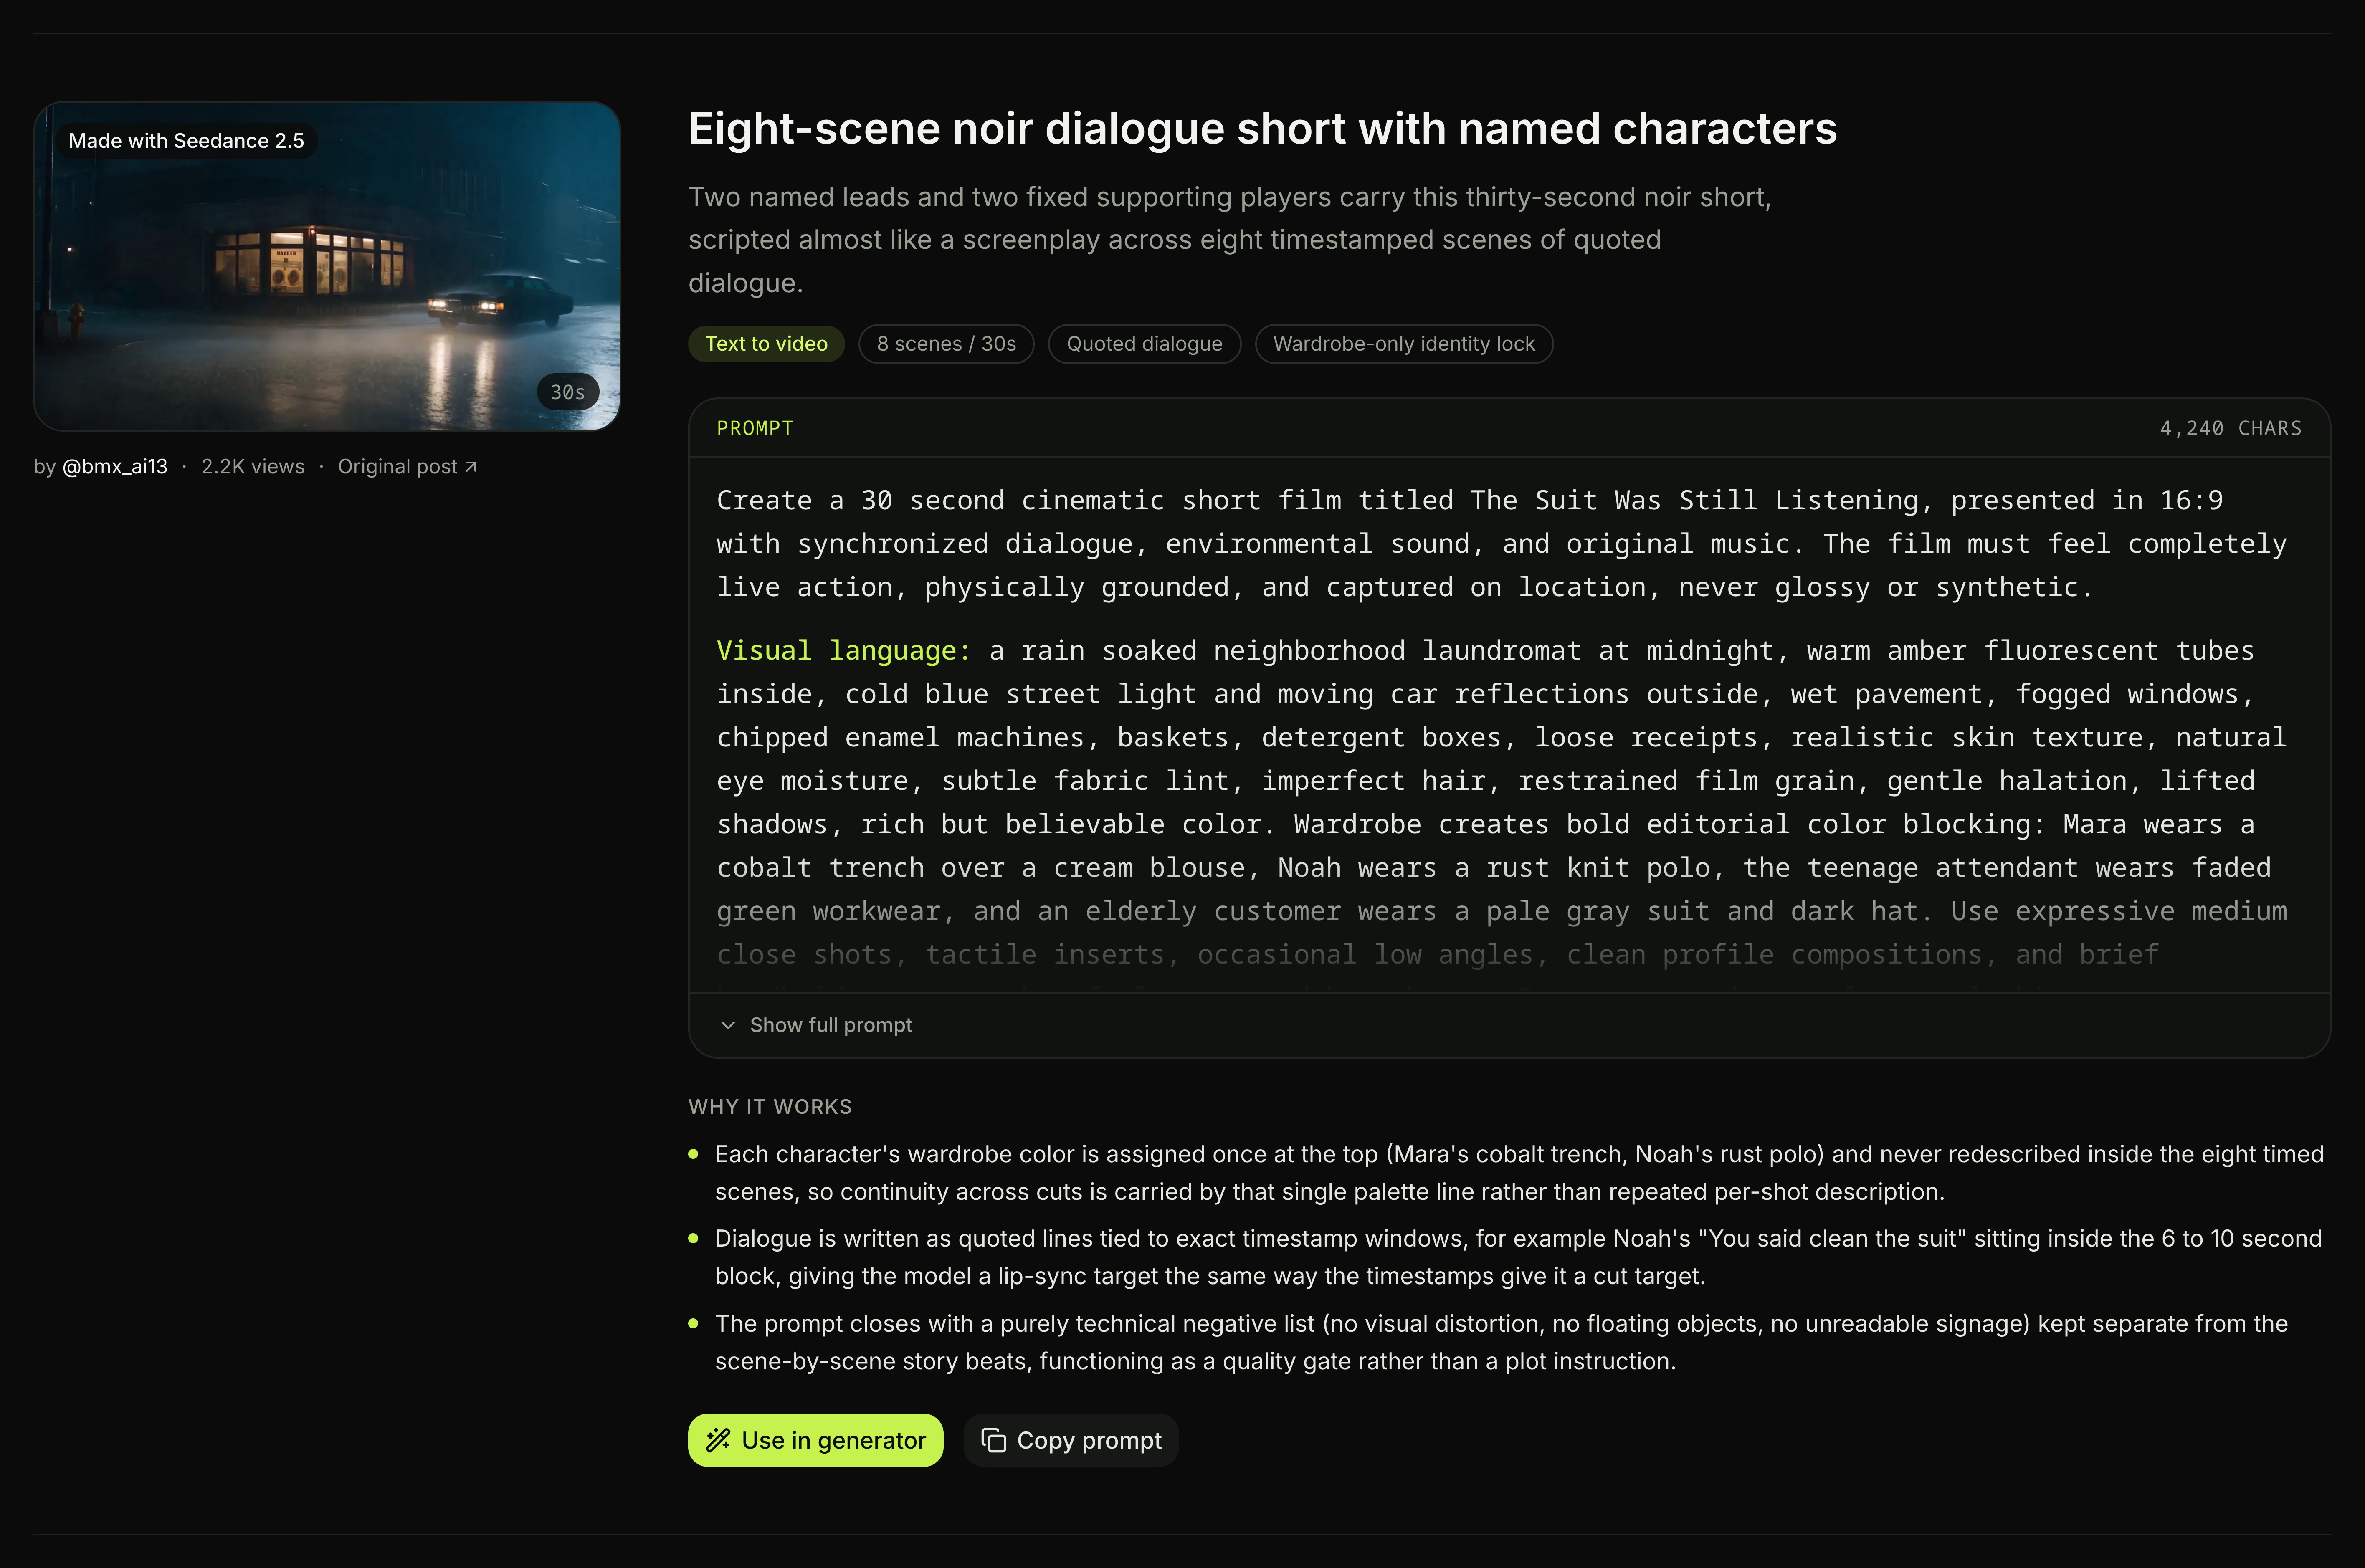
提示词库中的一张卡片:成片、制作者、完整提示词,以及我们认为它为何奏效的解析——截图截取于 2026年8月19日。
以下是我们的统计结果:
| 统计指标 | Seedance 2.5 提示词 (44) | Seedance 2.0 提示词 (21) | 对你的实际意义 |
|---|---|---|---|
| 平均词数 | 469 词 | 400 词 | 一条真正有效的提示词往往是一整段结构化文本,而不是一句话。 |
| 中位词数 | 401 词 | 412 词 | 其中一半的词数少于 400 词,说明长短并非决定性因素,结构才是关键。 |
| 包含时间码 | 41% | 29% | 自从模型能够识别时间戳后,创作者开始普遍在提示词中加入时间规划。 |
| 撰写声音指令 | 45% | 19% | 当模型具备原生音频生成能力后,声音设计便成为了提示词的核心组成部分。 |
| 指定镜头焦段 | 45% | 29% | 专业的镜头术语输入成本极低,且能精准生效。 |
| 结尾包含“禁止项”列表 | 36% | 43% | 负向约束依然存在,但 2.5 对无意义负向词的依赖大幅减少。 |
统计于 2026年8月19日,数据来源于提示词库背后的开源数据集。
在这 44 条提示词中,32% 包含了带引号的台词,45% 明确指定了镜头或焦距。其中最长的一条提示词达到了 12,790 个字符。该长度已经超出了我们编辑框 10,000 字符的限制,因此在复制某些外部长提示词时需要先做适当删减。
以下是从我们的提示词库中精选的三种提示词结构:
1. 秒表级控时的 20 拍调度(@sebatheepan,2026年8月1日)
保洁员、天文馆以及突然具象化变为实体的月球。该提示词由 20 个镜头组成,每个镜头都以中括号时间跨度开头:[0–1.5s] Shot 1:、[1.5–3s] Shot 2:,依此类推。结尾用一个总结段落锁定全局风格,并明确禁止出现“文字、额外人物或毫无缘由的瞬间移动”。
由 @sebatheepan 使用 Seedance 2.5 制作,2026年8月1日。
2. 完全不借助参考图的 30 秒长镜(@VeraVCreates,2026年8月1日) 这是收录数据中最长的一条提示词,多达 1,939 个词。由于没有上传任何素材,每一条规则都必须依赖文字详述:包括“OVERALL STYLE”(全局风格)板块、“UNIFIED COLOR PALETTE”(统一色调)板块、“MAIN CHARACTER”(主角设定)板块,以及一条贯穿四个场景的连续飞行运镜轨迹。这就是纯靠文字维持角色一致性所必需付出的提示词成本。
由 @VeraVCreates 使用 Seedance 2.5 制作,2026年8月1日。
3. 镜头无缝延展(@digitalwindai,2026年7月31日) 这是一个用于视频延展(Extension)的提示词。其亮点在于罗列了跨接片段中必须继承保留的元素:骑手的身份特征、头盔与面罩、调色风格,以及“以相同调性、节奏与编曲无缝持续,不重新开头”(continues unbroken in the same key, tempo and arrangement with no restart)的配乐。延展功能目前仅支持在 API 端调用,Seadanse 暂未上线,但这篇提示词的架构方式依然极具参考价值。
由 @digitalwindai 使用 Seedance 2.5 制作,2026年7月31日。
你可以在我们的提示词库中一键将这些完整提示词载入生成器。
5 个导致废片的常见错误
错误使用镜头编号而非时间戳
写“Shot 1”会让节奏完全随机,因为 2.5 依赖整秒级时间戳。请明确使用类似 0-4 seconds 的时间跨度,将关键拍牢牢锁定在时间轴上。
参考图未标明对应关系
未加标注的图片会导致角色面部特征混淆或凭空多出多余人物。在描述具体动作之前,请先用单行明确绑定关系,如 Image 1 is Mara。
时间线上出现空白断档
如果你的时间线从 0-3 seconds 直接跳到了 6-10 seconds,模型就必须自行脑补中间空缺的情节。请保持时间区间的连贯闭合,以保证转场平滑。
在极短时间内堆砌过多动作
试图在 3 秒的时间窗口内塞进 5 个肢体动作,必然会导致画面疯狂乱切或关键动作丢失。请给每一个核心动作留出足够的秒数。
滥用宽泛的负向提示词
输入“无模糊、无崩坏肢体”这类的负向字符串会被模型完全忽略。该模型仅支持针对字幕和音频的负向否定,请用正向陈述句来描述画面细节。
Seadanse 当前暂不支持的提示词功能
- 最高分辨率上限为 1080p: 无论是在 API 还是在 Seadanse 上,2.5 都不支持 4K 生成。我们详细解析了完整的分辨率规格阶梯以及所谓“原生 4K”说法的由来。
- 不支持参考音频输入: 你可以向 Seedance 2.5 提交图片和视频,但不能上传声音文件,因此无法指定特定声音让其模仿。如果你有该项需求,Wan 3.0 AI 视频生成器支持输入音频参考。
- 支持 6 种固定宽高比,无法任意自定义比例: 你只能在
16:9、9:16、1:1、4:3、3:4和21:9之间选择。在 API 端,宽高比可支持 0.4 到 2.5 之间的任意数值,但这一数值并非手动输入,而是通过上传该比例的参考图自动继承得来的。 - 多格分镜仅供参考: 模型不会逐帧严格执行多格分镜板的构图,因此分镜数量最好保持在 15 格以内。
- 复杂人体交互依然存在难度: ByteDance 研究团队指出,复杂的多人肢体交互目前依然是模型的短板所在。
开始撰写提示词
想要发挥出模型的最佳生成效果,请坚持使用四段式结构:明确绑定素材文件、概括场景概要、按时间戳排布节奏拍,并确立声音与一致性规则。
- 复制上文中的任意一个模板。
- 打开 Seedance 2.5 生成器。
- 将参数设置为 720p 和 10 秒。
- 点击“生成”,即可制作你的成片。
常见问题解答
Seedance 2.5 的提示词写多长合适?
根据我们的统计,有效提示词的平均长度为 469 词,中位数为 401 词。这一篇幅足以让你清晰地绑定参考素材、排布动作节奏、指导原生音效并设定精确的运镜轨迹。
时间戳真的能起作用吗?
可以,Seedance 2.5 能够直接解析整秒级的时间范围。像 0-3 seconds 或 4-8 seconds 这样的时间跨度,能将特定动作和运镜路径精准锁定在时间轴的相应节点上。
我能直接套用 Seedance 2.0 的旧提示词吗?
部分可以迁移,但大多数需要重构。Seedance 2.0 AI 图生视频 依靠镜头编号而非时间戳运作,且不支持多视角参考素材输入,因此按照新结构调整提示词后效果会好得多。
模型会自动生成我没有要求的背景音乐吗?
会的——音频默认开启,除非你明确要求关闭。如果你只需要角色对白和环境背景音而不需要配乐,请在声音板块中加上“No music”或“No BGM”。
相关文章
- 什么是 Seedance 2.5?字节跳动 30 秒视频模型深度解析——在开始为其撰写提示词前,先了解该模型的核心机制。
- Seedance 2.5 分辨率:实测 480p、720p 与 1080p,而非 4K——揭秘其真实的分辨率规格阶梯。
- Higgsfield 上的 Seedance 2.5 无限模式:33 天条款细则实测——探究其他平台所谓“无限模式”背后的实际限制。
- 2026 年 7 款最佳 Runway 替代工具实测与横评——全面对比 Seedance 与同类产品的竞争力。


