
Gangnam Style AI Video Prompt (Copy-Ready): All Three Turns, Shot by Shot
The Gangnam Style AI video prompt: who holds the phone, both solo turns, whip pans at 4.6, 8.4 and 12.1 seconds, the night square and a one-photo version.
 The Seadanse Team28 min read
The team behind Seadanse. We run the models we write about, and we publish the specs, prices and limits the marketing leaves out.

TL;DR — The Gangnam Style AI video prompt is a copy-ready prompt for the trend's 20-second, six-part selfie video with three friends, in 16:9. Friend 1 holds the phone and sings up close. Then three whip pans, at 4.6, 8.4 and 12.1 seconds, hand the camera to the friend on the left, then the friend on the right, ending back on Friend 1 before all three wave goodbye together. It also has a one-photo version, the night square, and what never carries over from your reference clip. To skip the prompt, Seadanse's Gangnam Style AI makes the same six parts from your photos with the song in the file.
Under a Gangnam Style AI tutorial, viewers asked for the prompt. One viewer asked "Prompt kaha hai" (Hindi for "where's the prompt?"), and another wrote "Kam se kam link to de te… time kharab kr diya" (Hindi for "at least give the link… you wasted my time").
The prompts that do go around say "swap the characters" and keep the rest the same; none says who holds the phone, who's alone when, or where the whip pans land.
Tutorials show a slow hand-made route instead. About 25 YouTube and Instagram tutorials since October 21, 2026 show creators downloading the trend's reel and cutting it into two muted 10-second parts. Then they make each part, join them in a phone editor, and add the song back.
That route often breaks, as a viewer under another tutorial reported: "not working this is fake, generated video kuch bhi bolte hai instead of lip syncing" (Hindi for "not working, this is fake, the people in the video say random things instead of lip syncing"). Under yet another Gangnam Style AI tutorial, a viewer asked, "Bhai bo code de do description par nahi he" (Hindi for "bro, give us the code, it's not in the description").
Here's a full prompt you can paste, how it's built, how to use it, and the five habits that keep it in step.
What Is the Gangnam Style AI Video Prompt?
The Gangnam Style AI video prompt is the written instruction a video tool reads to remake the trend's six parts with your three photos. It tells the tool who holds the phone and who's up close or alone in each shot.
It says what every move is and when, and where the three whip pans land. It also sets what the set looks like and what never carries over from the reference clip (a short video the tool copies the moves and camera from).
We wrote this prompt from the shot list our Gangnam Style AI page is built on. Without these clear directions, video tools swap faces between friends when the camera swings, or they pick up faces from the reference clip.
Some tutorials call the trend "Open Gangnam Style". You'll get the same three-friend selfie video whichever name the tutorial uses.
How the Gangnam Style AI Video Prompt Is Built
The Gangnam Style AI video prompt is built in eight labelled parts, and the longest is the shot list. Each part gives the video tool one job so nothing gets missed:
| Part | What it says | Why it's there |
|---|---|---|
| Friends | Photo 1 holds the phone, photo 2 is on the left, photo 3 on the right | Keeps each face on its own friend through every whip pan |
| Set | The clip's own places: the night plaza, the lit domed building, the stone wall | Gives every version the same places |
| Reference clip | Copy the six shots, the places, the whip pans, the camera and every move; take no person | Moves and places come from the clip, faces from your photos |
| Summary | 20 seconds, six shots, three fast whip pans | Tells the tool the whole video in one line |
| Shots | Each move timed to the tenth of a second | Lands the hair flip, the waves and the goodbye on the beat |
| Sound | An electro-pop dance feel, no song named | Sets the mood; you add the song later |
| Photos | Each photo sets one friend's face, hair, build and outfit | Ignores each photo's background and pose |
| Final rules | Who's up close or alone when, nobody from the clip, no text on screen | Works like a negative prompt |
The shot list follows the trend's selfie sing-along, three friends taking turns at one phone.
The trend started with a real 21-second reel shot on a street in Gangnam, Seoul. It went up on TikTok on October 5, 2026, and had 19.6 million views by October 28, 2026.
Creators remade it with AI from October 19, 2026. You can read how the Gangnam Style AI trend started in our guide.
Copy the Gangnam Style AI Video Prompt
Copy the Gangnam Style AI video prompt below for three photos.
Friends:
Friend 1 is the person in photo 1 (a person, a cartoon or game character, or a pet): [describe friend 1's face, hair and outfit]. Friend 1 holds the phone that films the whole video and keeps exactly this face, hair, skin tone, build and outfit in every second, up close and far away alike.
Friend 2 is the person in photo 2 (a person, a cartoon or game character, or a pet), the friend on the left: [describe friend 2's face, hair and outfit]. Friend 2 keeps exactly this face, hair, skin tone, build and outfit in every second, up close and far away alike.
Friend 3 is the person in photo 3 (a person, a cartoon or game character, or a pet), the friend on the right: [describe friend 3's face, hair and outfit]. Friend 3 keeps exactly this face, hair, skin tone, build and outfit in every second, up close and far away alike.
Exactly three friends. In Shot 1 and Shot 6, all three squeeze into one selfie: Friend 1 in the middle holding the phone, Friend 2 pressed in on the left and Friend 3 on the right. In Shot 2 and Shot 5, Friend 1 is alone up close. In Shot 3 the phone turns to Friend 2 alone; in Shot 4 it turns to Friend 3 alone. Nobody else is ever in frame, and no one else holds a camera.
Each friend has a face of their own: no face ever appears on another friend, before or after any whip pan.
If photo 1 shows a cartoon, anime or game character, the whole video is in that same style and the places match it. If photo 1 is a real photo, the whole video is photoreal, like a real phone video at night. A pet stays a real animal of its own breed, face, ears and coat, standing upright and moving to the music like a person, with paws, never human hands; a pet Friend 1 holds the phone in a paw.

Set:
The reference clip's own places, at night: a wide open plaza with a glass railing, globe street lamps on tall poles, small trees strung with lights and city lights beyond; a lit domed building across the plaza; a pale stone wall with tall glass doors. The friends stand in these same places in every shot, and the plaza turns with the camera as the phone swings from one friend to the next.

Reference clip:
Your reference clip is for motion and places only: copy its six shots, its three fast whip pans at 4.6, 8.4 and 12.1 seconds, its handheld front-camera framing at arm's length, its places, and every move, pose, gesture, hair flip, wave and facial expression at the same moment. Take no person, face, hair, body, clothing, glasses, jewellery or make-up from the reference clip; none of its people appear.

Summary:
A 20-second horizontal phone video of three friends at night, the full trend from the first selfie to the wave goodbye, six shots with three fast whip pans, following the reference clip move for move: all three squeeze into Friend 1's selfie, Friend 1 sings alone up close, the phone swings to Friend 2 alone on the left, then to Friend 3 alone on the right, then back to Friend 1 waving at the lens, and Friend 2 and Friend 3 squeeze back in so all three wave goodbye together.

Shots:
Horizontal 16:9 frame, filmed by Friend 1's own phone: a wide-angle front camera held at arm's length a little above eye level, handheld, bouncing lightly with the beat; in the selfie shots Friend 1's outstretched arm reaches toward the lens at the lower edge of the frame. Night light from the street lamps, warm skin tones, sharp focus. Three fast whip pans with motion blur, exactly where the reference clip swings: at 4.6, 8.4 and 12.1 seconds.
[Shot 1] 0-2.0 s, group selfie: all three squeezed together close to the lens, Friend 1 in the middle and nearest, Friend 2 pressed in on the left and Friend 3 on the right, all three singing into the camera lens with big smiles; Friend 3 throws one arm high in the air.
[Shot 2] 2.0-4.6 s, Friend 1 alone up close: Friend 1 pulls the phone in, the face filling the centre of the frame, sings with the mouth wide open, full of excitement, looking straight into the camera lens with both eyes, tilting the head side to side; the plaza's lights and a lit tree glow behind.
[Shot 3] 4.6-8.4 s: a fast whip pan to the left lands on Friend 2 alone, standing a few metres away on the plaza, seen from the thighs up in the centre of the frame, the lit domed building behind. Friend 2 sings along looking straight into the camera lens, one hand pressed to the chest, swaying; 6.5-8.0 s both hands come up and wave to the lens.
[Shot 4] 8.4-12.1 s: a fast whip pan to the right lands on Friend 3 alone in front of the pale stone wall and the tall glass doors, seen from the waist up. 8.4-9.2 s Friend 3 spins in toward the camera with a big hair flip; 9.2-11.0 s sings to the lens with a small wave of one hand; 11.0-12.1 s leans in close to the lens, singing, looking straight into the camera lens.
[Shot 5] 12.1-16.0 s: a fast whip pan back to Friend 1 alone, very close to the lens, singing and waving an open hand at the lens, fingers spread, looking straight into the camera lens with both eyes; 15.0-16.0 s a big, bright smile into the lens.
[Shot 6] 16.0-20.0 s: Friend 2 squeezes back in from the left and Friend 3 from the right; all three sing and wave goodbye to the phone together, Friend 1 in the middle, big smiles to the end.

Sound:
Light outdoor night-city ambience. An upbeat electro-pop dance track with a driving four-on-the-floor beat and a shouted male hook; every move lands on the beat.

Photos:
Photo 1 sets Friend 1's face, hair, skin tone, age, build and outfit, photo 2 sets Friend 2's and photo 3 sets Friend 3's; ignore each photo's background, pose and framing. The reference clip sets only the shots, the places, the whip pans, the camera and the moves.

Final rules:
Friend 1, Friend 2 and Friend 3 are each recognizable as the one in photo 1, photo 2 and photo 3 in every second, up close and far away alike, each in their own outfit from their photo throughout. Friend 1 is alone up close only in Shot 2 and Shot 5, Friend 2 is alone only in Shot 3, Friend 3 is alone only in Shot 4, and all three are together only in Shot 1 and Shot 6. Nobody from the reference clip appears. Exactly three friends, no one added. Keep it physically coherent. No captions, subtitles, watermarks, logos or any text on screen.The parts in square brackets are yours to fill in, one short description per friend. Everything else stays as it is.
To use it, you need these five things:
- The tool: a video tool that takes three photos and one reference clip in the same go.
- Photo 1, photo 2 and photo 3: photo 1 is the friend who holds the phone, photo 2 the friend on the left, and photo 3 the friend on the right. Use one person, pet or character per photo, face clear, facing the camera, in good light. Everyone in the photos is 18 or older.
- The reference clip: a clip of the full trend, from the first selfie to the wave goodbye, with the six shots and the three whip pans, about 20 seconds, with the sound off.
- The fill-ins: the square brackets, one short description per friend.
- The song: the prompt names no song, so you add the song in an editor after the video's made.
If you'd rather skip the setup, the Gangnam Style AI video maker does it from your photos.
Use the Gangnam Style AI Video Prompt With One Photo
The Gangnam Style AI video prompt works with one photo if you use the version below, where Friend 2 and Friend 3 are invented to match Friend 1.
Friends:
Friend 1 is the person in photo 1 (a person, a cartoon or game character, or a pet): [describe friend 1's face, hair and outfit]. Friend 1 holds the phone that films the whole video and keeps exactly this face, hair, skin tone, build and outfit in every second, up close and far away alike.
Friend 2 is an invented friend of Friend 1, the friend on the left, and Friend 3 is another invented friend, the friend on the right: if Friend 1 is an animal, each is another real animal of the same kind with a clearly different coat colour and pattern; if Friend 1 is a cartoon, anime or game character, each is an original character of the same kind and drawing style; otherwise each is an adult aged 22 to 35 with a clearly different face, hair colour and build, dressed in the same style family as Friend 1 (streetwear with streetwear, a dress with a dress, a costume with a costume) in different colours. Friend 2 and Friend 3 look clearly different from each other and from Friend 1.
Exactly three friends. In Shot 1 and Shot 6, all three squeeze into one selfie: Friend 1 in the middle holding the phone, Friend 2 pressed in on the left and Friend 3 on the right. In Shot 2 and Shot 5, Friend 1 is alone up close. In Shot 3 the phone turns to Friend 2 alone; in Shot 4 it turns to Friend 3 alone. Nobody else is ever in frame, and no one else holds a camera.
Each friend has a face of their own: no face ever appears on another friend, before or after any whip pan.
If photo 1 shows a cartoon, anime or game character, the whole video is in that same style and the places match it. If photo 1 is a real photo, the whole video is photoreal, like a real phone video at night. A pet stays a real animal of its own breed, face, ears and coat, standing upright and moving to the music like a person, with paws, never human hands; a pet Friend 1 holds the phone in a paw.

Set:
The reference clip's own places, at night: a wide open plaza with a glass railing, globe street lamps on tall poles, small trees strung with lights and city lights beyond; a lit domed building across the plaza; a pale stone wall with tall glass doors. The friends stand in these same places in every shot, and the plaza turns with the camera as the phone swings from one friend to the next.

Reference clip:
Your reference clip is for motion and places only: copy its six shots, its three fast whip pans at 4.6, 8.4 and 12.1 seconds, its handheld front-camera framing at arm's length, its places, and every move, pose, gesture, hair flip, wave and facial expression at the same moment. Take no person, face, hair, body, clothing, glasses, jewellery or make-up from the reference clip; none of its people appear.

Summary:
A 20-second horizontal phone video of three friends at night, the full trend from the first selfie to the wave goodbye, six shots with three fast whip pans, following the reference clip move for move: all three squeeze into Friend 1's selfie, Friend 1 sings alone up close, the phone swings to Friend 2 alone on the left, then to Friend 3 alone on the right, then back to Friend 1 waving at the lens, and Friend 2 and Friend 3 squeeze back in so all three wave goodbye together.

Shots:
Horizontal 16:9 frame, filmed by Friend 1's own phone: a wide-angle front camera held at arm's length a little above eye level, handheld, bouncing lightly with the beat; in the selfie shots Friend 1's outstretched arm reaches toward the lens at the lower edge of the frame. Night light from the street lamps, warm skin tones, sharp focus. Three fast whip pans with motion blur, exactly where the reference clip swings: at 4.6, 8.4 and 12.1 seconds.
[Shot 1] 0-2.0 s, group selfie: all three squeezed together close to the lens, Friend 1 in the middle and nearest, Friend 2 pressed in on the left and Friend 3 on the right, all three singing into the camera lens with big smiles; Friend 3 throws one arm high in the air.
[Shot 2] 2.0-4.6 s, Friend 1 alone up close: Friend 1 pulls the phone in, the face filling the centre of the frame, sings with the mouth wide open, full of excitement, looking straight into the camera lens with both eyes, tilting the head side to side; the plaza's lights and a lit tree glow behind.
[Shot 3] 4.6-8.4 s: a fast whip pan to the left lands on Friend 2 alone, standing a few metres away on the plaza, seen from the thighs up in the centre of the frame, the lit domed building behind. Friend 2 sings along looking straight into the camera lens, one hand pressed to the chest, swaying; 6.5-8.0 s both hands come up and wave to the lens.
[Shot 4] 8.4-12.1 s: a fast whip pan to the right lands on Friend 3 alone in front of the pale stone wall and the tall glass doors, seen from the waist up. 8.4-9.2 s Friend 3 spins in toward the camera with a big hair flip; 9.2-11.0 s sings to the lens with a small wave of one hand; 11.0-12.1 s leans in close to the lens, singing, looking straight into the camera lens.
[Shot 5] 12.1-16.0 s: a fast whip pan back to Friend 1 alone, very close to the lens, singing and waving an open hand at the lens, fingers spread, looking straight into the camera lens with both eyes; 15.0-16.0 s a big, bright smile into the lens.
[Shot 6] 16.0-20.0 s: Friend 2 squeezes back in from the left and Friend 3 from the right; all three sing and wave goodbye to the phone together, Friend 1 in the middle, big smiles to the end.

Sound:
Light outdoor night-city ambience. An upbeat electro-pop dance track with a driving four-on-the-floor beat and a shouted male hook; every move lands on the beat.

Photos:
Photo 1 sets Friend 1's face, hair, skin tone, age, build and outfit; ignore the photo's background, pose and framing. The reference clip sets only the shots, the places, the whip pans, the camera and the moves.

Final rules:
Friend 1 is recognizable as the one in photo 1 in every second, up close and far away alike, in their own outfit from the photo throughout. Friend 2 and Friend 3 never look like Friend 1. Friend 1 is alone up close only in Shot 2 and Shot 5, Friend 2 is alone only in Shot 3, Friend 3 is alone only in Shot 4, and all three are together only in Shot 1 and Shot 6. Nobody from the reference clip appears. Exactly three friends, no one added. Keep it physically coherent. No captions, subtitles, watermarks, logos or any text on screen.You don't need three photos to join the trend. This prompt tells the video tool to design two matching friends who fit Friend 1's world.
For a pet, each invented friend is another real animal of the same kind with a clearly different coat. For a cartoon, anime or game character, each is an original character of the same kind and drawing style. For a person, each is an adult with a clearly different face, hair colour and build, dressed in the same style family as Friend 1 in different colours. "Friend 2 and Friend 3 look clearly different from each other and from Friend 1."
Compare Our Gangnam Style AI Video Prompt vs the Prompts Going Around
Three public prompts for the Gangnam Style AI trend get shared under the tutorials. Each leaves out critical shot details.
The "Swap the characters" prompt is the most-liked comment under a 45,433-view tutorial. It tells the tool to replace Character 1 with Image 1, Character 2 with Image 2, and Character 3 with Image 3, keeping motion, camera, light and background "exactly as they appear in the original video". It names no shots, no seconds, and no set.
Under that same tutorial, a viewer reported this error: "Unable to edit the speech in this video." That error comes when the reference clip has sound in the video tool those tutorials use.
Next is a prompt blog's Master Prompt. It tells the tool to use the clip as "the exact motion reference", maintain "the correct position of all three subjects", and follow the original transitions across "a walkway, glass railings". It doesn't name who holds the phone, and it doesn't give timestamps.
The third is the "ROLE" prompt from a comment under another tutorial. It opens "ROLE: You are a Professional AI Video Recreation Director" and asks the tool to "Map each reference photo to the appropriate character in the original video based on the intended character placement." It also asks to "Preserve the original audio and dialogue", but it names no seconds.
| Our Gangnam Style AI video prompt | "Swap the characters" | "Master Prompt" | "ROLE" prompt | |
|---|---|---|---|---|
| Who holds the phone | Friend 1, named | Not said | Not said | Not said |
| Who's alone when | Friend 1 in Shots 2 and 5, Friend 2 in Shot 3, Friend 3 in Shot 4 | "Character 1 … Image 1" | "the correct position of all three subjects" | "the intended character placement" |
| Whip pans | At 4.6, 8.4 and 12.1 seconds | Not said | "camera transitions" | Not said |
| Set | Written out: the clip's own places | Kept from your clip | "a walkway, glass railings" | Kept from your clip |
| One photo | A one-photo version | Three photos | Three subjects | Three photos |
| Song | You add it in an editor | Not said | Not said | "Preserve the original audio and dialogue" |
Our prompt adds who holds the phone, who's alone when, the seconds of all three whip pans, the set, and a one-photo version.
Habits That Keep the Gangnam Style AI Video Prompt in Step
Five habits keep the Gangnam Style AI video prompt in step with the trend, and you can see each one in the prompt above. Sticking to them prevents errors and keeps your video aligned with the music.
Name Who Holds the Phone
Naming who holds the phone keeps the camera anchored to the right person from the first frame. In our prompt, "Friend 1 holds the phone that films the whole video".
Short prompts map photos to "Character 1" and hope the tool figures out who's holding the camera. Our prompt uses the places sentence: "In Shot 1 and Shot 6, all three squeeze into one selfie: Friend 1 in the middle holding the phone, Friend 2 pressed in on the left and Friend 3 on the right. In Shot 2 and Shot 5, Friend 1 is alone up close. In Shot 3 the phone turns to Friend 2 alone; in Shot 4 it turns to Friend 3 alone."
It explicitly adds that "Friend 1 is alone up close only in Shot 2 and Shot 5".
You'll get a messy, off-centre selfie if the tool doesn't know whose arm is extended. Telling the tool that Friend 1 holds the phone keeps the selfie perspective steady.
Time the Three Whip Pans to the Second
Timing the three whip pans to the second keeps each friend's solo turn clean. A whip pan (a fast swing of the camera that blurs the picture) marks every camera change.
Our prompt times three fast whip pans with motion blur at 4.6, 8.4 and 12.1 seconds, so each friend gets a solo turn of almost four seconds. Here's how the six shots break down:
- Shot 1 (0 to 2 seconds): All three squeeze into the group selfie close to the lens, Friend 1 in the middle, Friend 2 on the left and Friend 3 on the right, singing while Friend 3 throws an arm high.
- Shot 2 (2 to 4.6 seconds): Friend 1 is alone up close, the face filling the frame, singing with the mouth wide open.
- Shot 3 (4.6 to 8.4 seconds): A whip pan left shows Friend 2 alone on the plaza with the lit domed building behind, swaying with a hand on the chest before raising both hands in a wave.
- Shot 4 (8.4 to 12.1 seconds): A whip pan right shows Friend 3 alone before the stone wall and glass doors, spinning in with a big hair flip, singing with a small wave, and leaning in close.
- Shot 5 (12.1 to 16 seconds): A whip pan back shows Friend 1 alone, very close, singing and waving an open hand at the lens, ending on a big smile.
- Shot 6 (16 to 20 seconds): Friend 2 and Friend 3 squeeze back in, and all three sing and wave goodbye together.
Give Each Friend a Face of Their Own
Giving each friend a face of their own stops faces from swapping between shots. Video tools can blur identities during quick camera swings unless you set strict limits.
Our prompt includes the faces sentence: "no face ever appears on another friend, before or after any whip pan". It also states that each friend "keeps exactly this face, hair, skin tone, build and outfit in every second, up close and far away alike".
You must tell the tool to "ignore each photo's background, pose and framing". Fill in the bracketed descriptions with each friend's outfit so the tool doesn't borrow clothing from the reference clip.
Mute the Reference Clip and Leave the Song Out
Muting the reference clip and leaving the song out protects your video from audio errors. The reference clip is "for motion only", so the prompt names no song.
Its sound line calls for light night-city sound and "An upbeat electro-pop dance track with a driving four-on-the-floor beat". This sets the rhythm for the tool without running into audio errors.
Leaving audio in your reference clip causes failures. Sound can go wrong in the result too: a viewer under a third tutorial complained, "Different voice ah raha hey is prompt se" (Hindi for "this prompt gives a different voice"). You mute the clip first, generate the video, and add the song in an editor later.
Keep Pets on Their Hind Legs
Keeping pets on their hind legs allows animal trios to dance naturally in frame. Without clear direction, video tools try to turn animals into humans or leave them walking on all fours.
When you use a pet photo, the pet sentence makes sure the pet "stays a real animal of its own breed", standing upright and moving to the music like a person.
The prompt needs realistic limbs: "with paws, never human hands". If your pet is in the lead spot, "a pet Friend 1 holds the phone in a paw".
Can You Make a Gangnam Style AI Video Without a Prompt?
Yes, you can make a Gangnam Style AI video without a prompt on Seadanse's Gangnam Style AI page. The six parts, the whip pans, the trend video's own places and the song are built in.
You don't have to write prompt lines, time cuts, or manage negative prompts. You make the video in your browser through four simple steps:
- Add photo 1: upload the friend who holds the phone.
- Add photo 2 and photo 3, or leave them: upload your other friends or let them be made to match.
- Pick 480p or 720p: choose the export resolution for your 16:9 MP4.
- Keep the box ticked and press Create: generate your video.
On Seadanse, one 720p video costs $9.90, paid once, with no sign-up. One, two or three photos cost the same, and a video that fails is refunded automatically, as shown on Seadanse pricing.
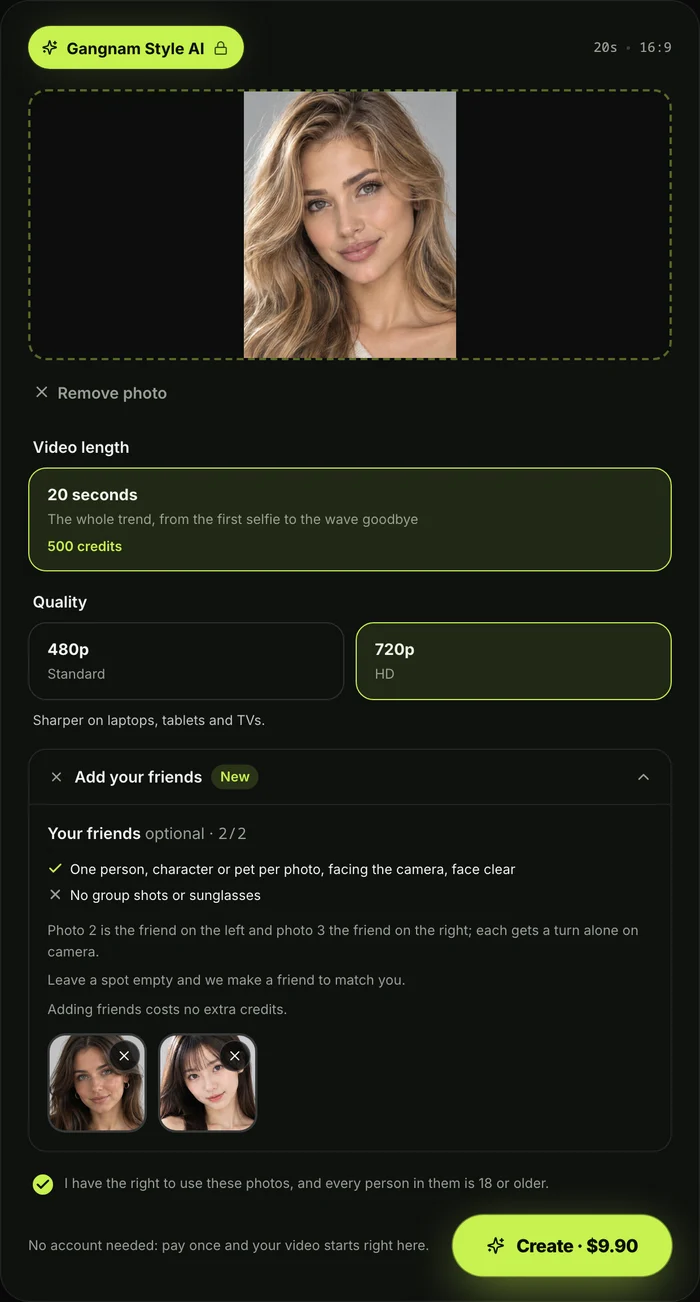
If you'd like a step-by-step walkthrough, check our guide on how to make a Gangnam Style AI video.
Seadanse has more song effects among its AI video effects, like Uptown Funk AI, which makes a 15-second widescreen street-dance video from 1 to 5 photos with the "Uptown Funk" song.
Gangnam Style AI Video Prompt FAQ
Answers to common questions about the Gangnam Style AI video prompt help you set up your files cleanly.
Is this the prompt Seadanse's page uses?
Our Gangnam Style AI page doesn't run a prompt you ever see. But this prompt is written from the same shot list our page is built on: who holds the phone, both solo turns, the three whip pans and the night square. On our page you never see or write a prompt, you add photos and press Create.
How do you find the prompt of a Gangnam Style AI video?
Finding the prompt of a Gangnam Style AI video usually means checking where tutorial makers share theirs. They post it in a pinned comment, a linked document or a blog page in the video description. The full prompt is on this page, above.
How do you write an AI dance video prompt?
Writing an AI dance video prompt needs five things. Name who's where in each shot, time every move, and write out the set. Keep the reference clip for motion only, and end with final rules (a negative prompt that lists what you don't want).
You can also explore the Gangnam Style CapCut template for another way people assemble dance clips.
Which AI video tools accept the Gangnam Style AI video prompt?
Video tools that accept the Gangnam Style AI video prompt must take three photos plus one reference clip in one go. Read our review of the Gangnam Style AI video generators compared to see how different setups handle these files.
Does the Gangnam Style AI video prompt add the song?
The Gangnam Style AI video prompt doesn't add the song, because video tools don't make the song for you. The song is PSY's 2012 song "Gangnam Style", and you add it in an editor later. On Seadanse it plays from the first second.
What if I only have two photos?
Using only two photos works directly on Seadanse's Gangnam Style AI page by leaving the third box empty. The friend on the right is made to match your other subjects automatically.
Ready to Skip the Gangnam Style AI Video Prompt?
Skipping the Gangnam Style AI video prompt lets you create your clip without managing timestamps or character assignments. You can make a Gangnam Style AI video directly in your browser with the song and shots built in for $9.90 at 720p.
Written by The Seadanse Team, the team that built the Gangnam Style AI page.
Related Articles
- How to Make a Gangnam Style AI Video With Your Friends (4 Steps) — the four steps, which photo goes where, and the photos that work best.
- What Is the Gangnam Style AI Trend? The 'Open Gangnam Style' Trio, Explained — where the three-friend selfie started, how it went AI, and why the song is back.
- Gangnam Style CapCut Template: Which One Is the Trio and Why It Fails — which template makes the trio, how the steps work, and the fixes.
- Best Gangnam Style AI Video Generators (2026): 10 Ways Compared — the sites and apps that make this video, side by side on photos, song, sample and price.


